First contact resolution was defined when a human picked up. It counted the share of contacts closed without a handoff, and it was a decent proxy for competence. Once an automated agent answers before anybody sees the ticket, the definition breaks in three places and the number flatters you.
TL;DR
- The old definition assumed a person answered. An agent that answers in two seconds makes almost every contact a first contact resolution by the letter of the rule.
- Worse, the contacts the agent handles are the easy ones, so the metric improves most when nothing about the hard work has changed.
- Rebuild it as three separate numbers, not one: agent resolved, human resolved first touch, and resolved after a handoff.
- A resolution is only a resolution if the person did not come back. Measure it over a 72-hour window or you are counting answers rather than outcomes.
- An escalation is not a failure. Counting it as one produces an agent that guesses instead of handing over, which is the expensive defect.
- Report the three-way split alongside repeat contact rate. Either number alone can be gamed and the pair cannot.
The three places the definition breaks
First, what counts as a contact. A question typed into a chat widget and answered instantly is a contact under the old rule, which means a desk that deflects 400 lookups a month has added 400 first contact resolutions without touching the queue. The rate goes up and the desk did not improve.
Second, what counts as resolved. An answer is not a resolution. The requester may have read it, misunderstood it, and solved the problem another way or not at all. When a human closed the ticket there was at least a judgement involved; an automated answer closes nothing and records a success.
Third, what counts as a handoff. The old metric penalised passing a ticket to a second person. An agent handing a sensitive or complex question to a human on the first attempt is doing exactly the right thing, and under the inherited rule it scores as a failure.
Why the number improves while nothing does
This is the part worth being blunt about. Automated agents handle the easy end of the distribution: password questions, how-do-I questions, where-is-the-form questions. Those were already the contacts most likely to be resolved on first touch.
So adding an agent moves a large block of already-easy contacts into a category that scores perfectly, while the hard contacts stay exactly where they were. The blended rate climbs, a report goes to a leadership meeting, and the only thing that changed is the mix.
The honest version of that report says the agent resolved a share of contacts, the human first-touch rate on what remains is a separate number, and here is whether that second number moved. Usually it has moved slightly downward, because the queue is now concentrated in genuinely harder work, and that is a good outcome being reported as a bad one.
The three-way split that replaces it
| Category | What it counts | What a change means |
| Agent resolved | Answered, and no return in 72 hours | Rising means the corpus is covering more |
| Agent escalated | Handed to a person deliberately | Rising is often correct, not a failure |
| Human first touch | Closed by the first person who saw it | Falling slightly is expected and fine |
| Resolved after handoff | Needed a second person or team | Rising points at routing, not skill |
| Returned within 72 hours | Came back regardless of who closed it | The only number that cannot be gamed |
Four categories and one cross-cutting check. The last row is the discipline: anything that came back inside three days was not resolved, whoever closed it, and subtracting those from the first three categories is what turns a count of answers into a count of outcomes.
The 72-hour rule
Pick a window and apply it to every category. Three days is the usual choice because it covers a weekend badly and a working week well, and because most genuine recurrences surface within it.
Then match on requester and intent rather than on the exact ticket. Somebody whose laptop problem was closed on Monday and who opens a new ticket about the same laptop on Wednesday has not had two tickets resolved, and matching on ticket identity will record exactly that.
What to do:
- Set a single return window, 72 hours, and use it for agent-resolved and human-resolved contacts alike.
- Match returns on requester plus intent, not on ticket identity, or a reopened problem reads as two successes.
- Report the three-way split every month and never a blended figure, because the blend only measures the mix.
- Stop counting escalation as failure. Track it as its own number with a target range rather than a target direction.
- Exclude agent-resolved contacts when reporting on human workload, and say so in the report rather than in a footnote.
Why penalising escalation is the expensive mistake
If escalation counts against the agent’s score, the configuration will be tuned to escalate less. That sounds like efficiency and it is the opposite: an agent discouraged from handing over will answer questions it should decline, which produces confident wrong answers on exactly the topics where being wrong costs most.
Set a range instead. An escalation rate near zero means the agent is overreaching, and a rate above a third means the corpus is too thin for the questions arriving. Somewhere between is healthy, and the useful review is reading ten escalations and asking whether each was the right call rather than watching the percentage.
Disclosure: Matram is owned by the same people who publish PeopleOpsHQ. It is relevant here because its strict mode declines rather than guessing, which makes the escalation number honest rather than suppressed, and it is priced flat at $29, $69 and $199 a month with unlimited seats rather than per agent. It has no free tier, it answers questions rather than actioning tickets, and it is not an ITSM platform, which means a declined question needs something behind it to receive the handoff. The options are compared in our IT support chatbot comparison.
Final thoughts
First contact resolution was a reasonable metric for a desk where a person answered the phone. It survives into automated support as a number that rises when the mix changes and stays flat when the work improves, which is the worst combination a metric can have.
Split it four ways, apply one return window to all of it, and stop treating a deliberate handoff as a failure. Then read the three-way split next to repeat contact rate, because each can be gamed alone and neither can be gamed while the other is in the same report.
Frequently asked questions
What is first contact resolution in IT support?
The share of contacts closed without being passed to anybody else, originally defined for desks where a person answered the phone and a handoff genuinely signalled that the first responder could not help. The definition assumes a human picked up, which is why it breaks once an automated agent answers first: by the letter of the rule almost every instant answer counts as a resolution.
Why does the metric improve when you add an AI agent?
Because agents handle the easy end of the distribution, which was already the part most likely to be resolved on first touch, so a large block of simple contacts moves into a category that scores perfectly while the hard work stays exactly where it was. The blended rate climbs purely because the mix changed, and the human first-touch rate on what remains usually dips slightly, which is a good outcome being reported as a bad one.
How should you measure resolution once a bot answers first?
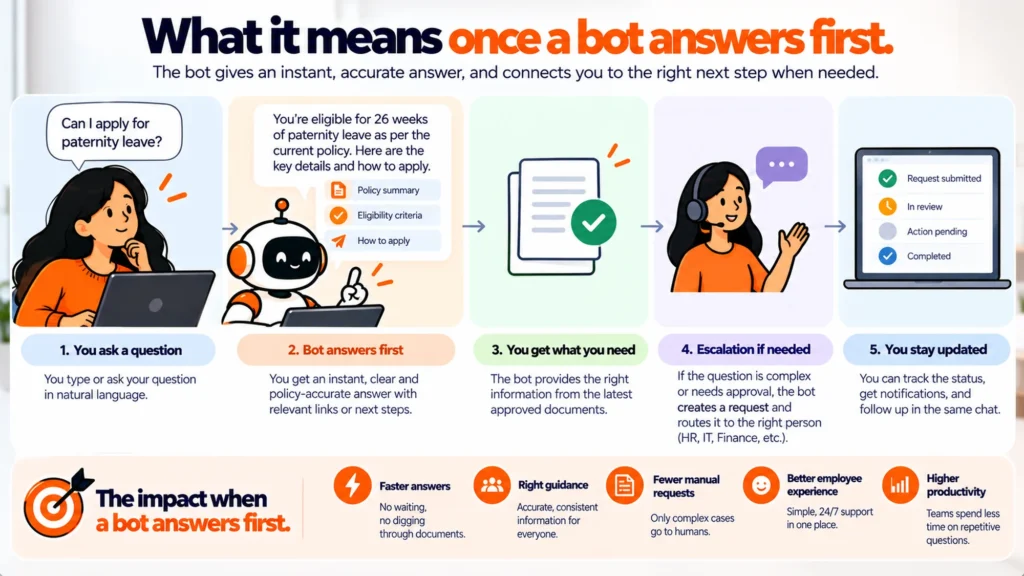
As four separate numbers rather than one: contacts the agent resolved, contacts the agent escalated deliberately, contacts closed by the first person who saw them, and contacts needing a second person or team. Then apply one return window across all four, because a blended figure measures only the proportion of easy contacts and will move whenever the mix does.
Why does the 72-hour window matter?
Because an answer is not a resolution until the person has not come back, and three days covers a working week well enough to catch most genuine recurrences. Match returns on the requester plus the intent rather than on ticket identity, since somebody whose laptop issue was closed on Monday and who opens a fresh ticket about the same laptop on Wednesday will otherwise be recorded as two separate successes.
Should escalation count against the agent?
No, and treating it as a failure is the most expensive configuration mistake available, because an agent tuned to escalate less will answer questions it should decline and produce confident wrong answers on the topics where being wrong costs most. Set a target range instead: near zero means it is overreaching, above about a third means the corpus is too thin, and the useful review is reading ten escalations to judge whether each was the right call.
Which two metrics should be reported together?
The resolution split and repeat contact rate, because each can be gamed on its own and neither can be while the other sits in the same report. A desk can inflate resolutions by closing tickets quickly, and that behaviour shows up immediately as people coming back, so the pair constrains each other in a way that no single headline number does.